
KampányMűvek / 8 October 2026
Backup audit: identify persistent data before writing the cron job
We began auditing the production directory layout and persistent state of five KampányMűvek-managed sites to make daily backup design follow real recovery needs.
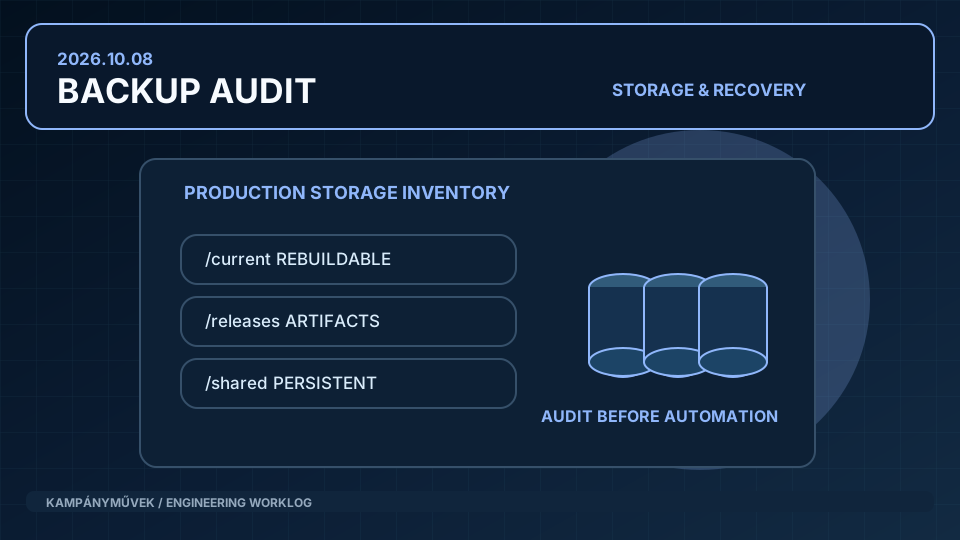
Situation
Several websites share the same Engine foundation, but that does not mean their backup requirements are identical. Static releases may be reproducible from Git and deployment artifacts, while uploads, runtime data, databases and secrets require separate recovery planning. A poorly targeted tar or rsync operation can produce a large backup that still cannot restore the service.
Approach
On the Websites server, we examined current, releases and shared directories per site, resolved the active release, reviewed storage usage, inspected Git worktree state and looked for likely persistent paths. This was the first step toward distinguishing rebuildable deployment artifacts from irreplaceable business state. The remaining design still needs clear retention, frequency, offsite replication and restore-test requirements.
Outcome
The storage and data inventory is under way and provides a foundation for a daily backup strategy. This is explicitly an audit milestone, not a fully automated or restore-tested backup system; no successful backup jobs are claimed.